
Ana içeriğe geç
black-forest-labs avatarı

FLUX.2 [dev] API

Metin prompt’undan güçlü prompt uyumu ve verimli, hızlı inference ile yüksek kaliteli görseller üretin.

görsel megapikseli başına 0.012

Model girdisi

Input

The text prompt describing the image to generate.

The size of the generated image. Choose a preset (e.g. '16_9_1k', '4_3_2k') or pass a custom {width, height} object.

Min: 4 - Max: 50

The number of inference steps to perform. More steps can improve detail at the cost of speed.

Additional Settings

Customize your input with more control.

Min: 0 - Max: 20

The CFG (Classifier Free Guidance) scale. Higher values increase adherence to the prompt.

The same seed and the same prompt given to the same version of the model will output the same image every time.

Min: 1 - Max: 4

The number of images to generate. Each generated image is billed.

You need to be logged in to run this model and view results.
Log in

Model çıktısı

Output

Generated image output
Generated in 2.956 seconds
Logs (1 lines)

Örnek istekler

Örnekler

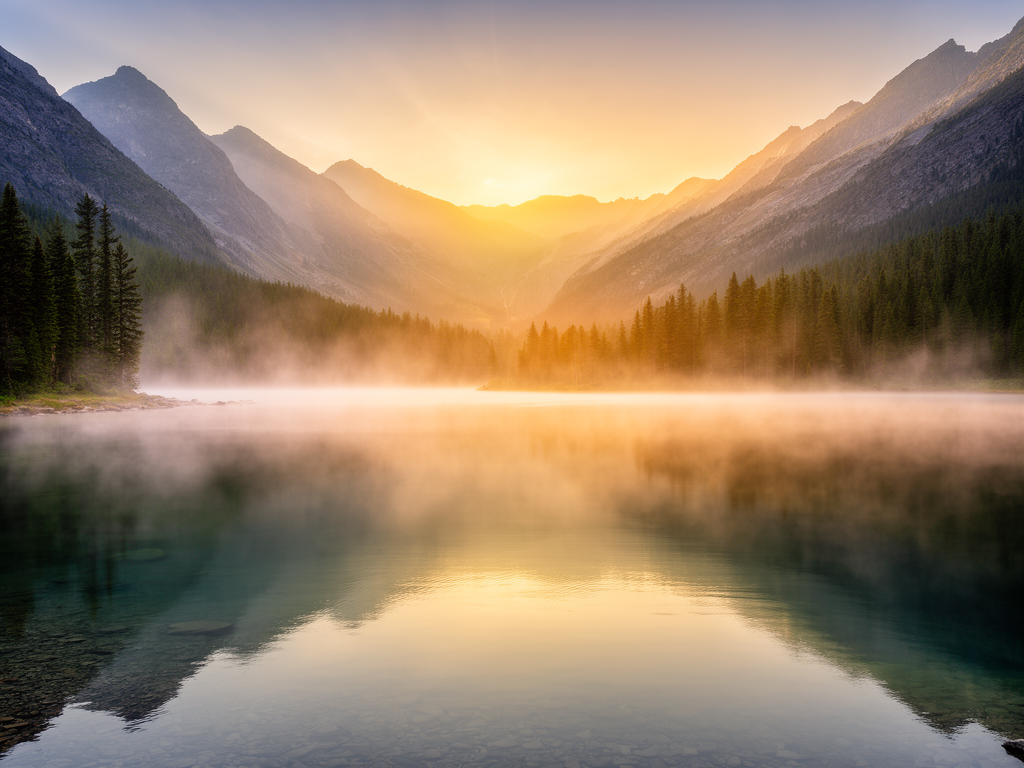
Example output 1Example output 2

FLUX.2 [dev] API

FLUX.2 [dev] is a text-to-image AI model by black-forest-labs. On ModelRunner it runs through a REST API or via MCP from any AI assistant, at $0.012 per megapixel.

POST https://queue.modelrunner.run/black-forest-labs/flux-2

cURL

# Submit a request to the queue. Input fields go at the top level of the
# body. The optional reserved "metadata" object holds your own flat string
# tags — stored on the request, never sent to the model; filter later with
# GET https://queue.modelrunner.run/requests?metadata=<url-encoded JSON>.
curl -X POST https://queue.modelrunner.run/black-forest-labs/flux-2 \
  -H "Authorization: Key $MRUN_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "prompt": "a serene mountain lake at golden hour, mist over the water, photorealistic",
    "image_size": "landscape_4_3",
    "num_images": 1,
    "guidance_scale": 2.5,
    "num_inference_steps": 28,
    "metadata": {
      "project": "my-project"
    }
  }'
# → { "request_id": "...", "status_url": "...", "response_url": "..." }

# Poll status_url until "COMPLETED", then fetch the result
curl "https://queue.modelrunner.run/black-forest-labs/flux-2/requests/$REQUEST_ID/status" \
  -H "Authorization: Key $MRUN_API_KEY"
curl "https://queue.modelrunner.run/black-forest-labs/flux-2/requests/$REQUEST_ID" \
  -H "Authorization: Key $MRUN_API_KEY"

JavaScript

import { modelrunner } from "@modelrunner/client";

const result = await modelrunner.subscribe("black-forest-labs/flux-2", {
  input: {
    "prompt": "a serene mountain lake at golden hour, mist over the water, photorealistic",
    "image_size": "landscape_4_3",
    "num_images": 1,
    "guidance_scale": 2.5,
    "num_inference_steps": 28
  },
});
console.log(result);

Python

import os
import requests

headers = {"Authorization": f"Key {os.environ['MRUN_API_KEY']}"}

submitted = requests.post(
    "https://queue.modelrunner.run/black-forest-labs/flux-2",
    headers=headers,
    json={
      "prompt": "a serene mountain lake at golden hour, mist over the water, photorealistic",
      "image_size": "landscape_4_3",
      "num_images": 1,
      "guidance_scale": 2.5,
      "num_inference_steps": 28
    },
).json()

# Poll submitted["status_url"] until "COMPLETED", then:
result = requests.get(submitted["response_url"], headers=headers).json()

Input parameters

Input parameters of FLUX.2 [dev]
NameTypeRequiredDescription
promptstringyesThe text prompt describing the image to generate.
image_sizeenumnoThe size of the generated image. Choose a preset (e.g. '16_9_1k', '4_3_2k') or pass a custom {width, height} object. One of: 1_1_1k, 1_1_2k, 16_9_1k, 16_9_2k, 9_16_1k, 9_16_2k, 4_3_1k, 4_3_2k, 3_4_1k, 3_4_2k, 3_2_1k, 3_2_2k, 2_3_1k, 2_3_2k, 21_9_1k, 21_9_2k. Default: "4_3_1k".
num_inference_stepsintegernoThe number of inference steps to perform. More steps can improve detail at the cost of speed. Default: 28.
guidance_scalenumbernoThe CFG (Classifier Free Guidance) scale. Higher values increase adherence to the prompt. Default: 2.5.
seedintegernoThe same seed and the same prompt given to the same version of the model will output the same image every time.
num_imagesintegernoThe number of images to generate. Each generated image is billed. Default: 1.

Machine-readable: OpenAPI schema · llms.txt

Use FLUX.2 [dev] from Claude & Cursor (MCP)

Point Claude Code, Claude Desktop, Cursor, or any MCP client at the ModelRunner MCP server and FLUX.2 [dev] becomes a tool your assistant can call directly — it authorizes via OAuth (no API key in config) and runs this model with the run_model tool using the endpoint black-forest-labs/flux-2.

MCP client config (Claude Desktop, Cursor)

{
  "mcpServers": {
    "modelrunner": {
      "command": "npx",
      "args": ["-y", "mcp-remote", "https://mcp.modelrunner.run/mcp"]
    }
  }
}

Claude Code

claude mcp add --transport http modelrunner https://mcp.modelrunner.run/mcp

Then ask your assistant, for example: “Run black-forest-labs/flux-2 on ModelRunner to generate image”. MCP setup guide.

Model Detayları

Model Detayları

FLUX.2 [dev], metin prompt’unu yüksek kaliteli bir görsele dönüştürür. Black Forest Labs imzalı, hafif ve verimli bir text-to-image modelidir: hızlı ve ucuz çalışırken güçlü prompt uyumunu ve görsel sadakatini korur. Bu da onu illüstrasyonlar, ürün çekimleri, konsept çizimler ve pazarlama görselleri için sağlam, genel amaçlı bir varsayılan seçim yapar. Ağır ve yavaş bir pipeline’la uğraşmadan tek bir prompt’tan temiz ve prompt’a sadık sonuçlar istediğinizde tercih edin.

## En uygun olduğu işler - Prompt’u sadakatle izleyen genel text-to-image üretimi — illüstrasyonlar, konsept çizimler, ürün ve editoryal sahneler - Birkaç prompt varyasyonunu kısa sürede görmek istediğiniz hızlı, düşük maliyetli yineleme - Bir açıklamadan üretilen pazarlama ve sosyal medya görselleri, arka planlar ve hero görseller - Toplu fikir üretimi: kompozisyonları karşılaştırmak için tek bir prompt’tan en fazla 4 görsel isteyin

## Şu durumlarda başka bir model seçin - Sıfırdan görsel üretmek yerine mevcut bir görseli düzenlemek, yeniden tarzlamak ya da değiştirmek istiyorsanız — bir görsel düzenleme / image-to-image modeli kullanın - Görseliniz büyük ölçüde, kusursuz okunaklı kalması gereken yoğun ya da çok satırlı tipografiden oluşuyorsa — görsel içinde metin basmada uzmanlaşmış bir model kullanın - Prompt’unuzdan video ya da animasyon istiyorsanız — bir text-to-video modeli kullanın

## İpuçları - Özne, kompozisyon, ışık ve stil konusunda net olun; FLUX.2 ayrıntılı prompt’ları yakından izler - `image_size` değerini yerleşime göre seçin: geniş sahneler için `landscape_16_9` ya da `landscape_4_3`, dikey için `portrait_4_3` / `portrait_16_9`, sosyal medya için `square` / `square_hd` - Tek bir çağrıda aynı prompt’tan birkaç varyasyon almak için `num_images` (1-4) kullanın - `guidance_scale` (varsayılan 2.5) yaratıcılıktan ödün vererek prompt uyumunu güçlendirir; hız pahasına daha fazla detay için `num_inference_steps` (varsayılan 28, en az 4) değerini yükseltin

## Sınırlamalar - Küçük puntolu uzun metin pasajları yine de glif hatalarına yol açabilir - Yüksek derecede fotogerçekçi yüzler ve eller ek bir düzenleme turu gerektirebilir

ModelRunner JavaScript client ile çalıştırmak için: ```js import { modelrunner } from "@modelrunner/client";

const result = await modelrunner.subscribe("black-forest-labs/flux-2", { input: { prompt: "a serene mountain lake at golden hour, mist over the water, photorealistic", image_size: "landscape_4_3", num_images: 1, }, }); ```