
Ana içeriğe geç
tencent avatarı

HunyuanImage 3.0 API

tencent/hunyuan-image/v3/text-to-image

Güçlü prompt uyumu ve uzun, ayrıntılı açıklamalar için geliştirilmiş 80 milyar parametreli bir modelle metin prompt’undan yüksek çözünürlüklü görseller üretin.

görsel megapikseli başına 0.1

Model girdisi

Input

The text prompt describing the image you want to generate.

The size of the generated image.

Min: 1 - Max: 4

The number of images to generate. Each generated image is billed.

The format of the generated image.

Additional Settings

Customize your input with more control.

Describe what you do NOT want to appear in the image.

Min: 1 - Max: 50

The number of denoising steps to perform.

Min: 1 - Max: 20

The CFG scale. Higher values increase adherence to the prompt.

Random seed for reproducible results. The same seed and prompt produce the same image; leave unset for a random seed.

Safety checker can only be disabled on API call

Whether to enable prompt expansion. This uses a large language model to expand the prompt with additional details while maintaining the original meaning.

You need to be logged in to run this model and view results.
Log in

Model çıktısı

Output

Generated image output
Generated in 109.369 seconds
Logs (1 lines)

Örnek istekler

Örnekler

Example output 1Example output 2Example output 3Example output 4Example output 5Example output 6

HunyuanImage 3.0 API

HunyuanImage 3.0 is a text-to-image AI model by tencent. On ModelRunner it runs through a REST API or via MCP from any AI assistant, at $0.1 per megapixel.

POST https://queue.modelrunner.run/tencent/hunyuan-image/v3/text-to-image

cURL

# Submit a request to the queue. Input fields go at the top level of the
# body. The optional reserved "metadata" object holds your own flat string
# tags — stored on the request, never sent to the model; filter later with
# GET https://queue.modelrunner.run/requests?metadata=<url-encoded JSON>.
curl -X POST https://queue.modelrunner.run/tencent/hunyuan-image/v3/text-to-image \
  -H "Authorization: Key $MRUN_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
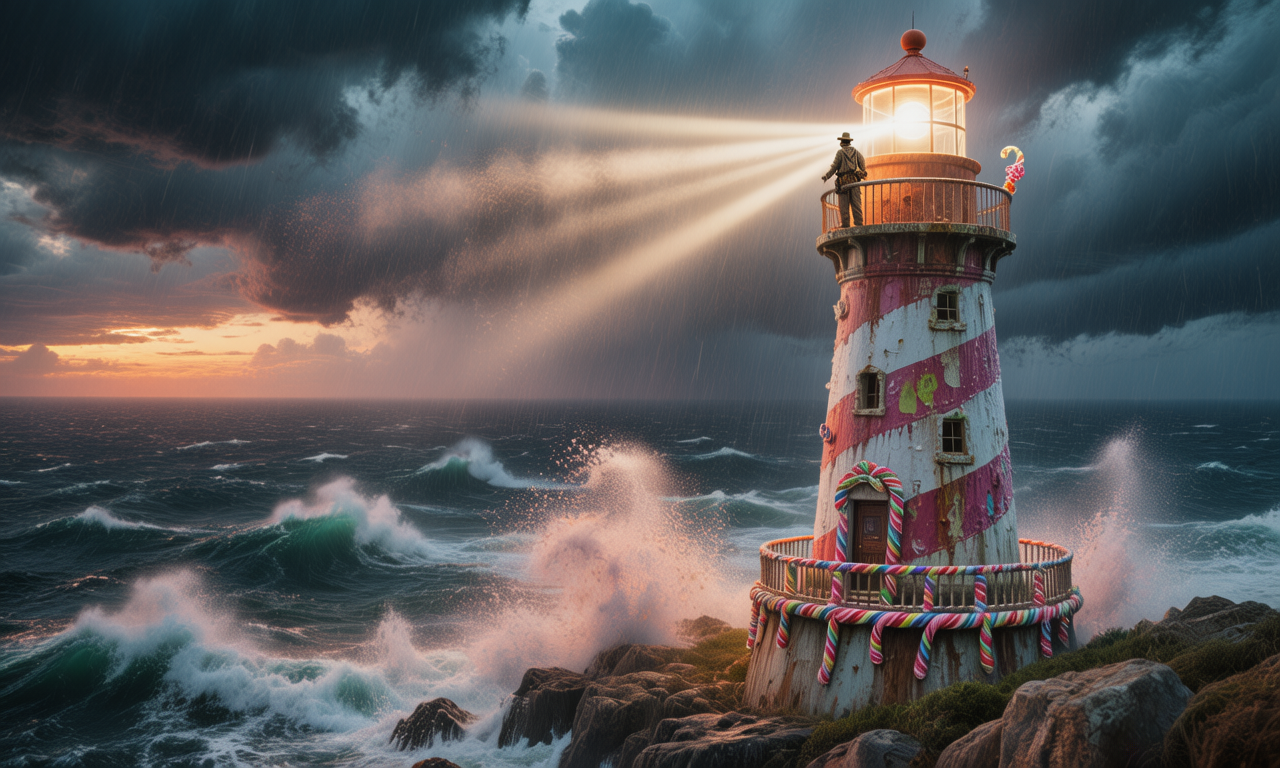
    "prompt": "A weathered lighthouse keeper standing at the top railing of a candy-striped lighthouse during a violent storm at dus…",
    "image_size": "landscape_16_9",
    "num_images": 1,
    "output_format": "png",
    "guidance_scale": 7.5,
    "negative_prompt": "",
    "num_inference_steps": 28,
    "enable_safety_checker": true,
    "enable_prompt_expansion": false,
    "metadata": {
      "project": "my-project"
    }
  }'
# → { "request_id": "...", "status_url": "...", "response_url": "..." }

# Poll status_url until "COMPLETED", then fetch the result
curl "https://queue.modelrunner.run/tencent/hunyuan-image/v3/text-to-image/requests/$REQUEST_ID/status" \
  -H "Authorization: Key $MRUN_API_KEY"
curl "https://queue.modelrunner.run/tencent/hunyuan-image/v3/text-to-image/requests/$REQUEST_ID" \
  -H "Authorization: Key $MRUN_API_KEY"

JavaScript

import { modelrunner } from "@modelrunner/client";

const result = await modelrunner.subscribe("tencent/hunyuan-image/v3/text-to-image", {
  input: {
    "prompt": "A weathered lighthouse keeper standing at the top railing of a candy-striped lighthouse during a violent storm at dus…",
    "image_size": "landscape_16_9",
    "num_images": 1,
    "output_format": "png",
    "guidance_scale": 7.5,
    "negative_prompt": "",
    "num_inference_steps": 28,
    "enable_safety_checker": true,
    "enable_prompt_expansion": false
  },
});
console.log(result);

Python

import os
import requests

headers = {"Authorization": f"Key {os.environ['MRUN_API_KEY']}"}

submitted = requests.post(
    "https://queue.modelrunner.run/tencent/hunyuan-image/v3/text-to-image",
    headers=headers,
    json={
      "prompt": "A weathered lighthouse keeper standing at the top railing of a candy-striped lighthouse during a violent storm at dus…",
      "image_size": "landscape_16_9",
      "num_images": 1,
      "output_format": "png",
      "guidance_scale": 7.5,
      "negative_prompt": "",
      "num_inference_steps": 28,
      "enable_safety_checker": true,
      "enable_prompt_expansion": false
    },
).json()

# Poll submitted["status_url"] until "COMPLETED", then:
result = requests.get(submitted["response_url"], headers=headers).json()

Input parameters

Input parameters of HunyuanImage 3.0
NameTypeRequiredDescription
promptstringyesThe text prompt describing the image you want to generate.
image_sizeenumnoThe size of the generated image. One of: square_hd, square, portrait_4_3, portrait_16_9, landscape_4_3, landscape_16_9. Default: "square_hd".
num_imagesintegernoThe number of images to generate. Each generated image is billed. Default: 1.
output_formatenumnoThe format of the generated image. One of: jpeg, png. Default: "png".
negative_promptstringnoDescribe what you do NOT want to appear in the image. Default: "".
num_inference_stepsintegernoThe number of denoising steps to perform. Default: 28.
guidance_scalenumbernoThe CFG scale. Higher values increase adherence to the prompt. Default: 7.5.
seedintegernoRandom seed for reproducible results. The same seed and prompt produce the same image; leave unset for a random seed.
enable_safety_checkerbooleannoIf set to true, the safety checker will be enabled. Default: true.
enable_prompt_expansionbooleannoWhether to enable prompt expansion. This uses a large language model to expand the prompt with additional details while maintaining the original meaning. Default: false.

Machine-readable: OpenAPI schema · llms.txt

Use HunyuanImage 3.0 from Claude & Cursor (MCP)

Point Claude Code, Claude Desktop, Cursor, or any MCP client at the ModelRunner MCP server and HunyuanImage 3.0 becomes a tool your assistant can call directly — it authorizes via OAuth (no API key in config) and runs this model with the run_model tool using the endpoint tencent/hunyuan-image/v3/text-to-image.

MCP client config (Claude Desktop, Cursor)

{
  "mcpServers": {
    "modelrunner": {
      "command": "npx",
      "args": ["-y", "mcp-remote", "https://mcp.modelrunner.run/mcp"]
    }
  }
}

Claude Code

claude mcp add --transport http modelrunner https://mcp.modelrunner.run/mcp

Then ask your assistant, for example: “Run tencent/hunyuan-image/v3/text-to-image on ModelRunner to generate image”. MCP setup guide.

Model Detayları

Model Detayları

HunyuanImage 3.0, metin prompt’unu yüksek kaliteli bir görsele dönüştürür. Güçlü prompt uyumu için geliştirilmiş, açık ağırlıklı büyük bir görsel temel modelidir (80 milyar parametre) ve uzun, ayrıntılı açıklamaların hakkını verir — özneyi, kompozisyonu, ışığı ve stili tek bir prompt’ta ayrıntılı biçimde yazabilir, sonucun bunları yakından izlemesini bekleyebilirsiniz. En-boy oranını `image_size` ile ayarlayın (`square_hd`, `portrait_16_9`, `landscape_16_9` gibi hazır ayarlar ya da açıkça bir `{width, height}`) ve `num_images` ile çağrı başına en fazla dört varyasyon üretin.

## En uygun olduğu işler - Ayrıntılı bir yazılı açıklamadan fotogerçekçi ve stilize görseller - Özne, sahne, ışık ve atmosferin hepsinin yerine oturması gereken uzun, zengin ayrıntılı prompt’lar - Bir brief’ten konsept çizim, editoryal illüstrasyon, poster ve pazarlama görselleri - Aralarından seçim yapmak için aynı anda birkaç kompozisyon varyantı üretmek - Sosyal medya, baskı ya da web yerleşimleri için kare olmayan en-boy oranlarında text-to-image işleri

## Şu durumlarda başka bir model seçin - Sıfırdan üretmek yerine mevcut bir görseli düzenlemek, yeniden tarzlamak ya da değiştirmek istiyorsanız — bir görsel düzenleme modeli kullanın - Dönüştürmek istediğiniz bir referans fotoğraf varsa ve yapısını korumak istiyorsanız — bir image-to-image modeli kullanın - En ucuz ve en hızlı taslaklar gerekiyorsa ve biraz sadakatten ödün verebiliyorsanız — damıtılmış, hızlı bir text-to-image modeli kullanın - Video gerekiyorsa — bir text-to-video ya da image-to-video modeli kullanın

## İpuçları - Özgül ve betimleyici prompt’lar yazın; model kısa anahtar kelime listelerinden çok özne, kompozisyon ve stile dair ayrıntıyı ödüllendirir - Kısa bir prompt’u amacını koruyarak bir dil modeline detaylandırtmak için `enable_prompt_expansion` alanını açın — kısa brief’lerde işe yarar; tam olarak yazdığınız ifadenin korunmasını istiyorsanız kapalı bırakın - Yaygın en-boy oranları için `image_size` hazır ayarlarını kullanın ya da tuvali tam olarak belirlemek için açıkça bir `{width, height}` nesnesi verin - Üretilen her görsel megapiksel başına faturalanır; bu yüzden daha büyük boyutlar ve daha yüksek `num_images` daha pahalıya gelir

ModelRunner JavaScript client ile çalıştırmak için: ```js import { modelrunner } from "@modelrunner/client";

const result = await modelrunner.subscribe("tencent/hunyuan-image/v3/text-to-image", { input: { prompt: "a snow leopard on a rocky ledge at golden hour, telephoto compression, sharp fur detail, cinematic lighting", image_size: "landscape_16_9", num_images: 1, output_format: "png", }, }); ```