
Ana içeriğe geç
qwen avatarı

Qwen-Image API

qwen/qwen-image

Metin prompt’undan yüksek kaliteli görseller üretin — asıl farkı, görselin içine İngilizce ve Çince metni doğru ve okunaklı basması.

görsel megapikseli başına 0.02

Model girdisi

Input

The text prompt describing the image to generate. Put any words you want rendered inside the image in quotes.

The size of the generated image. Use a preset string (e.g. 'landscape_16_9') or a custom {width, height} object.

Min: 2 - Max: 250

The number of inference steps to perform. More steps can improve detail at the cost of speed.

Additional Settings

Customize your input with more control.

Min: 0 - Max: 20

The CFG (Classifier Free Guidance) scale. Higher values increase adherence to the prompt.

The same seed and the same prompt given to the same version of the model will output the same image every time.

Min: 1 - Max: 4

The number of images to generate. Each generated image is billed.

You need to be logged in to run this model and view results.
Log in

Model çıktısı

Output

Generated image output
Generated in 27.006 seconds
Logs (1 lines)

Örnek istekler

Örnekler

Example output 1Example output 2

Qwen-Image API

Qwen-Image is a text-to-image AI model by qwen. On ModelRunner it runs through a REST API or via MCP from any AI assistant, at $0.02 per megapixel.

POST https://queue.modelrunner.run/qwen/qwen-image

cURL

# Submit a request to the queue. Input fields go at the top level of the
# body. The optional reserved "metadata" object holds your own flat string
# tags — stored on the request, never sent to the model; filter later with
# GET https://queue.modelrunner.run/requests?metadata=<url-encoded JSON>.
curl -X POST https://queue.modelrunner.run/qwen/qwen-image \
  -H "Authorization: Key $MRUN_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
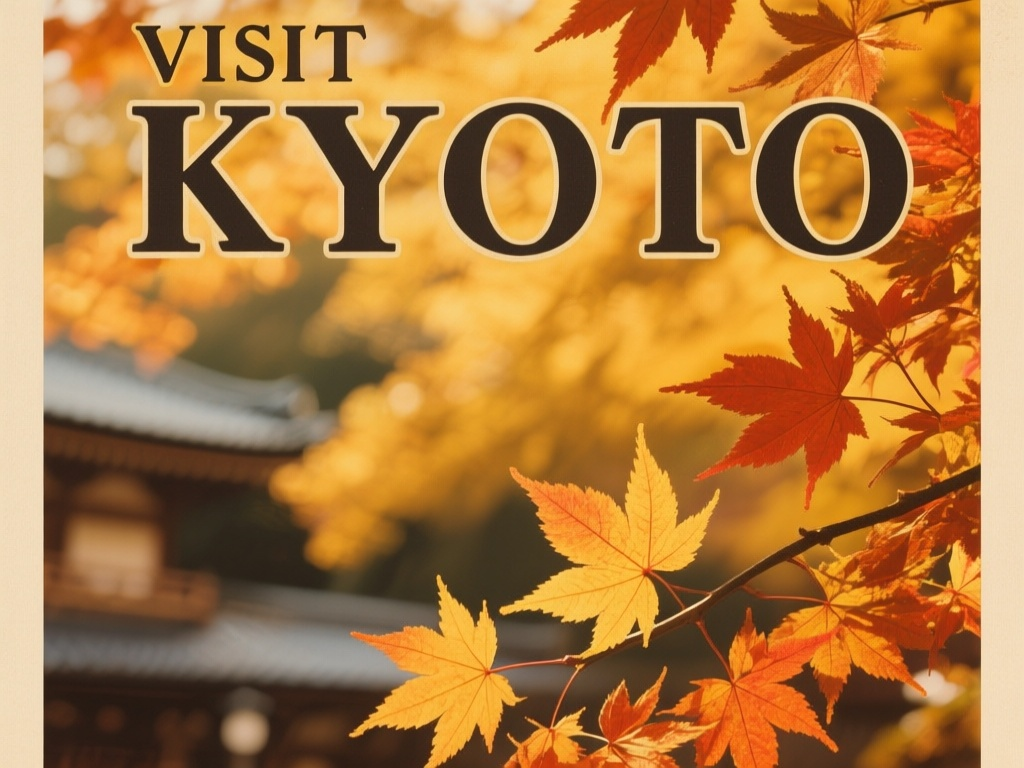
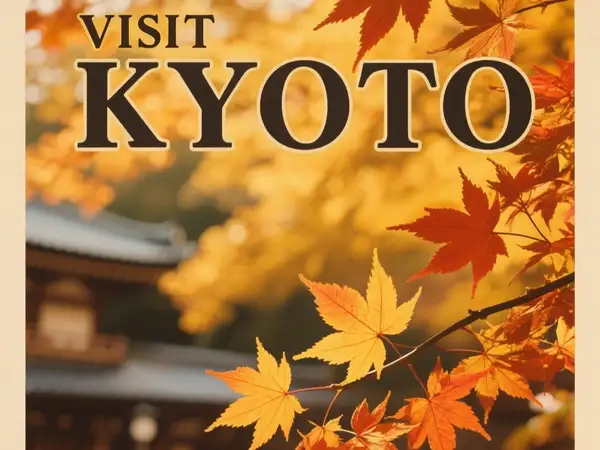
    "prompt": "a vintage travel poster with the headline \"VISIT KYOTO\" in bold serif type, autumn maple leaves, warm golden tones",
    "image_size": "landscape_4_3",
    "num_images": 1,
    "guidance_scale": 2.5,
    "num_inference_steps": 30,
    "metadata": {
      "project": "my-project"
    }
  }'
# → { "request_id": "...", "status_url": "...", "response_url": "..." }

# Poll status_url until "COMPLETED", then fetch the result
curl "https://queue.modelrunner.run/qwen/qwen-image/requests/$REQUEST_ID/status" \
  -H "Authorization: Key $MRUN_API_KEY"
curl "https://queue.modelrunner.run/qwen/qwen-image/requests/$REQUEST_ID" \
  -H "Authorization: Key $MRUN_API_KEY"

JavaScript

import { modelrunner } from "@modelrunner/client";

const result = await modelrunner.subscribe("qwen/qwen-image", {
  input: {
    "prompt": "a vintage travel poster with the headline \"VISIT KYOTO\" in bold serif type, autumn maple leaves, warm golden tones",
    "image_size": "landscape_4_3",
    "num_images": 1,
    "guidance_scale": 2.5,
    "num_inference_steps": 30
  },
});
console.log(result);

Python

import os
import requests

headers = {"Authorization": f"Key {os.environ['MRUN_API_KEY']}"}

submitted = requests.post(
    "https://queue.modelrunner.run/qwen/qwen-image",
    headers=headers,
    json={
      "prompt": "a vintage travel poster with the headline \"VISIT KYOTO\" in bold serif type, autumn maple leaves, warm golden tones",
      "image_size": "landscape_4_3",
      "num_images": 1,
      "guidance_scale": 2.5,
      "num_inference_steps": 30
    },
).json()

# Poll submitted["status_url"] until "COMPLETED", then:
result = requests.get(submitted["response_url"], headers=headers).json()

Input parameters

Input parameters of Qwen-Image
NameTypeRequiredDescription
promptstringyesThe text prompt describing the image to generate. Put any words you want rendered inside the image in quotes.
image_sizeenumnoThe size of the generated image. Use a preset string (e.g. 'landscape_16_9') or a custom {width, height} object. One of: square_hd, square, portrait_4_3, portrait_16_9, landscape_4_3, landscape_16_9. Default: "landscape_4_3".
num_inference_stepsintegernoThe number of inference steps to perform. More steps can improve detail at the cost of speed. Default: 30.
guidance_scalenumbernoThe CFG (Classifier Free Guidance) scale. Higher values increase adherence to the prompt. Default: 2.5.
seedintegernoThe same seed and the same prompt given to the same version of the model will output the same image every time.
num_imagesintegernoThe number of images to generate. Each generated image is billed. Default: 1.

Machine-readable: OpenAPI schema · llms.txt

Use Qwen-Image from Claude & Cursor (MCP)

Point Claude Code, Claude Desktop, Cursor, or any MCP client at the ModelRunner MCP server and Qwen-Image becomes a tool your assistant can call directly — it authorizes via OAuth (no API key in config) and runs this model with the run_model tool using the endpoint qwen/qwen-image.

MCP client config (Claude Desktop, Cursor)

{
  "mcpServers": {
    "modelrunner": {
      "command": "npx",
      "args": ["-y", "mcp-remote", "https://mcp.modelrunner.run/mcp"]
    }
  }
}

Claude Code

claude mcp add --transport http modelrunner https://mcp.modelrunner.run/mcp

Then ask your assistant, for example: “Run qwen/qwen-image on ModelRunner to generate image”. MCP setup guide.

Model Detayları

Model Detayları

Qwen-Image, bir metin prompt’unu yüksek kaliteli bir görsele dönüştürür. En güçlü yanı, doğru ve okunaklı metni doğrudan görselin içine basmasıdır — onu benzersiz kılan da hem İngilizce hem Çince metinle başa çıkması; çoğu görsel modelinin bozduğu yoğun, çok satırlı yerleşimler de buna dahil. Güçlü prompt uyumuyla birleşince, resimdeki kelimelerin resmin kendisi kadar önemli olduğu işlerde güvenilir bir tercihtir: posterler, tabelalar, ambalajlar, sosyal medya grafikleri ve iki dilli tasarımlar.

## En uygun olduğu işler - Başlıkların ve gövde metninin doğru yazılmış ve okunaklı kalması gereken posterler, el ilanları ve tabelalar - Çizimi gerçek kelimelerle bir araya getiren logolar, ürün etiketleri ve ambalaj mockup’ları - Doğru CJK glifleri gerektiren iki dilli ya da Çince tasarımlar (vitrinler, menüler, açıklama yazıları) - Prompt’a sadık kalan genel text-to-image sahneleri — illüstrasyonlar, ürün çekimleri, konsept çizimler

## Şu durumlarda başka bir model seçin - Sıfırdan üretmek yerine mevcut bir görseli düzenlemek, yeniden tarzlamak ya da değiştirmek istiyorsanız — bir görsel düzenleme / image-to-image modeli kullanın - Tam bu iş için geliştirilmiş bir modelin daha iyi tutturduğu fotogerçekçi portreler ya da niş bir estetik gerekiyorsa - Prompt’unuzdan video ya da animasyon istiyorsanız — bir text-to-video modeli kullanın

## İpuçları - Basılmasını istediğiniz kelimeleri prompt’ta birebir ve tırnak içinde yazın, yerlerini de tarif edin ("üzerinde ... yazan kırmızı bir banner" / "... yazan bir tabela") - Yerleşime uygun bir `image_size` seçin: posterler/banner’lar için `landscape_16_9`, tabelalar için `portrait_4_3`, sosyal medya için `square`; ya da özel bir `{ width, height }` nesnesi verin - Tek bir prompt’tan tek çağrıda birkaç varyasyon almak için `num_images` (1-4) kullanın - `guidance_scale` (varsayılan 2.5) yaratıcılıktan ödün vererek prompt uyumunu artırır; hız pahasına daha fazla detay için `num_inference_steps` değerini (varsayılan 30) yükseltin

## Sınırlamalar - Çok uzun metin pasajları ya da çok küçük puntolar yine de glif hatalarına yol açabilir - Son derece fotogerçekçi yüzler ve eller ek bir düzenleme geçişi gerektirebilir

ModelRunner JavaScript client ile çalıştırmak için: ```js import { modelrunner } from "@modelrunner/client";

const result = await modelrunner.subscribe("qwen/qwen-image", { input: { prompt: "a vintage travel poster with the headline \"VISIT KYOTO\" in bold serif type, autumn maple leaves", image_size: "landscape_4_3", num_images: 1, }, }); ```