
openai avatar

GPT Image 2.5 Sunburst Edit API

openai/gpt-image-2.5/sunburst/edit

Edit an existing image from a text instruction with the tightest control in the GPT Image 2.5 line — the change stays scoped to exactly what you asked and subject and composition hold across repeated revision passes, with optional masking and a second reference image for compositing.

edit
0.0556

Model Input

Input

The edit instruction. Name the single change you want, then list what must stay the same — subject, layout, lighting, wording. Put any words you want rendered inside the image in quotes.

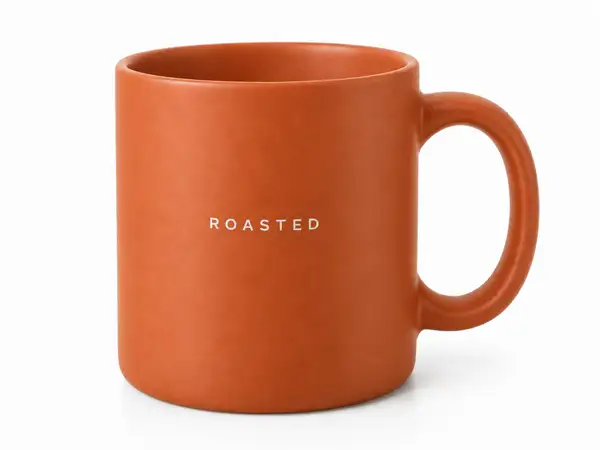
  • https://media.modelrunner.ai/U1Itf0AKXBZWtaWnG2B4q.png
  • https://media.modelrunner.ai/skieQLvVA4OZ14YuADAWA.png

One or two reference images. With one, the edit is applied to it; with two, elements from both can be combined into a single scene — address them in the prompt as 'image 1' and 'image 2'.

Additional Settings

Customize your input with more control.

Optional mask restricting the edit to one region. The mask should carry an alpha channel — transparent areas mark where changes are allowed — and match the reference image's size and format. Masking is prompt-guided, so the edited area may not follow the mask's shape exactly.

The aspect ratio and framing of the edited image. Match it to the source image's own aspect ratio unless you want the frame re-composed.

Min: 1 - Max: 4

How many edited images to generate from this request. Each image is charged as its own generation.

The file format of the edited image.

You need to be logged in to run this model and view results.
Log in

Model Output

Output

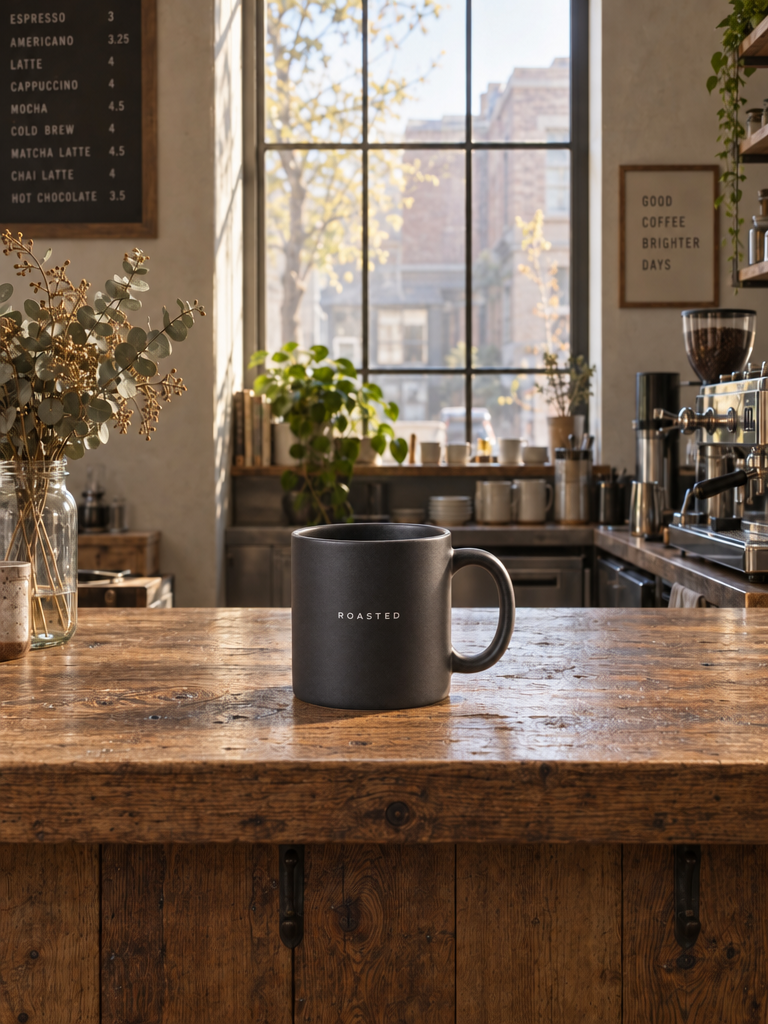
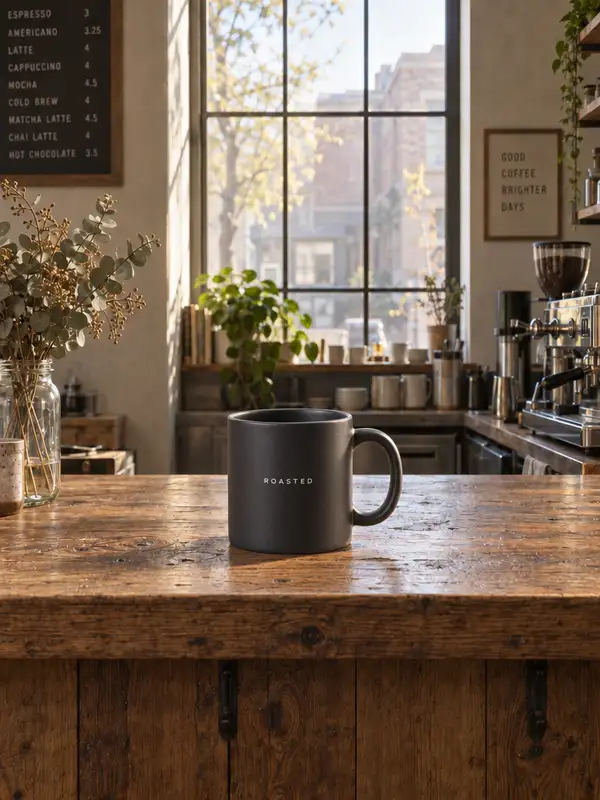
Generated image output
Generated in 32.279 seconds
Logs (1 lines)

Model Example Requests

Examples

Example output 1Example output 2

GPT Image 2.5 Sunburst Edit API

GPT Image 2.5 Sunburst Edit is a image-to-image AI model by openai. On ModelRunner it runs through a REST API or via MCP from any AI assistant, at $0.0556 per image.

POST https://queue.modelrunner.run/openai/gpt-image-2.5/sunburst/edit

cURL

# Submit a request to the queue. Input fields go at the top level of the
# body. The optional reserved "metadata" object holds your own flat string
# tags — stored on the request, never sent to the model; filter later with
# GET https://queue.modelrunner.run/requests?metadata=<url-encoded JSON>.
curl -X POST https://queue.modelrunner.run/openai/gpt-image-2.5/sunburst/edit \
  -H "Authorization: Key $MRUN_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "prompt": "Image 1 is the subject: the charcoal ceramic mug with \"ROASTED\" printed on its side. Image 2 is the location: the rus…",
    "image_size": "portrait_4_3",
    "image_urls": [
      "https://media.modelrunner.ai/U1Itf0AKXBZWtaWnG2B4q.png",
      "https://media.modelrunner.ai/skieQLvVA4OZ14YuADAWA.png"
    ],
    "num_images": 1,
    "output_format": "png",
    "metadata": {
      "project": "my-project"
    }
  }'
# → { "request_id": "...", "status_url": "...", "response_url": "..." }

# Poll status_url until "COMPLETED", then fetch the result
curl "https://queue.modelrunner.run/openai/gpt-image-2.5/sunburst/edit/requests/$REQUEST_ID/status" \
  -H "Authorization: Key $MRUN_API_KEY"
curl "https://queue.modelrunner.run/openai/gpt-image-2.5/sunburst/edit/requests/$REQUEST_ID" \
  -H "Authorization: Key $MRUN_API_KEY"

JavaScript

import { modelrunner } from "@modelrunner/client";

const result = await modelrunner.subscribe("openai/gpt-image-2.5/sunburst/edit", {
  input: {
    "prompt": "Image 1 is the subject: the charcoal ceramic mug with \"ROASTED\" printed on its side. Image 2 is the location: the rus…",
    "image_size": "portrait_4_3",
    "image_urls": [
      "https://media.modelrunner.ai/U1Itf0AKXBZWtaWnG2B4q.png",
      "https://media.modelrunner.ai/skieQLvVA4OZ14YuADAWA.png"
    ],
    "num_images": 1,
    "output_format": "png"
  },
});
console.log(result);

Python

import os
import requests

headers = {"Authorization": f"Key {os.environ['MRUN_API_KEY']}"}

submitted = requests.post(
    "https://queue.modelrunner.run/openai/gpt-image-2.5/sunburst/edit",
    headers=headers,
    json={
      "prompt": "Image 1 is the subject: the charcoal ceramic mug with \"ROASTED\" printed on its side. Image 2 is the location: the rus…",
      "image_size": "portrait_4_3",
      "image_urls": [
        "https://media.modelrunner.ai/U1Itf0AKXBZWtaWnG2B4q.png",
        "https://media.modelrunner.ai/skieQLvVA4OZ14YuADAWA.png"
      ],
      "num_images": 1,
      "output_format": "png"
    },
).json()

# Poll submitted["status_url"] until "COMPLETED", then:
result = requests.get(submitted["response_url"], headers=headers).json()

Input parameters

Input parameters of GPT Image 2.5 Sunburst Edit
NameTypeRequiredDescription
promptstringyesThe edit instruction. Name the single change you want, then list what must stay the same — subject, layout, lighting, wording. Put any words you want rendered inside the image in quotes.
image_urlsarrayyesOne or two reference images. With one, the edit is applied to it; with two, elements from both can be combined into a single scene — address them in the prompt as 'image 1' and 'image 2'.
mask_urlstring (uri)noOptional mask restricting the edit to one region. The mask should carry an alpha channel — transparent areas mark where changes are allowed — and match the reference image's size and format. Masking is prompt-guided, so the edited area may not follow the mask's shape exactly.
image_sizeenumnoThe aspect ratio and framing of the edited image. Match it to the source image's own aspect ratio unless you want the frame re-composed. One of: square_hd, square, portrait_4_3, portrait_16_9, landscape_4_3, landscape_16_9. Default: "landscape_4_3".
num_imagesintegernoHow many edited images to generate from this request. Each image is charged as its own generation. Default: 1.
output_formatenumnoThe file format of the edited image. One of: jpeg, png, webp. Default: "png".

Machine-readable: OpenAPI schema · llms.txt

Use GPT Image 2.5 Sunburst Edit from Claude & Cursor (MCP)

Point Claude Code, Claude Desktop, Cursor, or any MCP client at the ModelRunner MCP server and GPT Image 2.5 Sunburst Edit becomes a tool your assistant can call directly — it authorizes via OAuth (no API key in config) and runs this model with the run_model tool using the endpoint openai/gpt-image-2.5/sunburst/edit.

MCP client config (Claude Desktop, Cursor)

{
  "mcpServers": {
    "modelrunner": {
      "command": "npx",
      "args": ["-y", "mcp-remote", "https://mcp.modelrunner.run/mcp"]
    }
  }
}

Claude Code

claude mcp add --transport http modelrunner https://mcp.modelrunner.run/mcp

Then ask your assistant, for example: “Run openai/gpt-image-2.5/sunburst/edit on ModelRunner to generate image”. MCP setup guide.

Model Details

Model Details

GPT Image 2.5 Sunburst Edit takes one or two reference images plus a written instruction and returns an edited image. It is the precision tier of the GPT Image 2.5 editing line: the change stays scoped exactly to the instruction, and subject and composition hold across many rounds of revision rather than drifting each pass. Add a mask to confine the change to one region, or pass a second reference to composite elements from both pictures into one scene.

## Best for - Revision-heavy work where a picture goes through several passes and must not drift - Changing, adding or removing one element — a colour, an object, a line of wording — while the rest stays as shot - Inpainting a marked region: filling or replacing just the area your mask covers - Compositing a subject from one picture into the scene or background of a second

## Choose another model when - You need fast turnaround or a high volume of edits — this tier trades generation time for control; use `openai/gpt-image-2.5/flare/edit` - There is no source image to work from — use `openai/gpt-image-2.5/sunburst/text-to-image` - The edit must land exactly on a mask boundary — masking is prompt-guided and may not follow the shape precisely - You need more than two reference images at once — use an editing model with a larger reference limit

## Tips - Separate the change from the constraints: say "change only X", then list what must stay — identity, layout, lighting, labels - Revising in passes? Feed the previous output back in as `image_urls` and restate the preserve-list each time - With two references, name them by role: "image 1" the scene, "image 2" the subject to insert - Match `image_size` to the source image's aspect ratio, or the frame gets re-composed - Give the mask an alpha channel, sized and formatted like the image it masks

## Limitations - Generation takes longer than the faster tier in this family — the trade for the extra control - Every request runs at the standard high-quality setting; the extra-detail tiers are not selectable - Each request is independent — there is no conversation state, so every pass must restate what to preserve - Content filtering applies to every request and cannot be relaxed

To run via the ModelRunner JavaScript client: ```js import { modelrunner } from "@modelrunner/client";

const result = await modelrunner.subscribe("openai/gpt-image-2.5/sunburst/edit", { input: { prompt: 'Change only the printed word on the mug to read "DECAF"; keep the mug, the backdrop, lighting and framing exactly as they are.', image_urls: ["https://media.modelrunner.ai/U1Itf0AKXBZWtaWnG2B4q.png"], image_size: "landscape_4_3", output_format: "png", }, }); ```