
Model Details
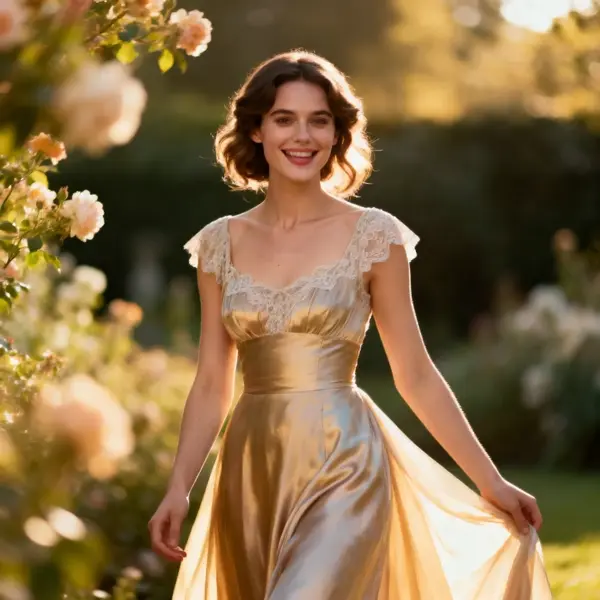
OmniHuman 1.5 turns a single still photo of a person and an audio track into a talking-head video: the subject's mouth, expression, and head/body motion are animated to match the speech or singing in the audio, with an optional text prompt to steer the overall motion and performance. Provide a clear portrait plus the audio you want them to deliver and you get back an MP4 of that person speaking it. Its strength is tight audio-driven lip and facial sync with believable, non-robotic body movement from just one image.
## Best for - Turning a headshot or portrait into a spokesperson video that lip-syncs to a voiceover or narration - Avatar and digital-presenter clips for explainers, ads, training, and product demos - Making a character or illustration sing or speak in time with a supplied audio track - Localized/dubbed talking-head clips where you already have the translated audio - Quick social or UGC-style talking-head content from a single photo plus audio
## Choose another model when - You already have a talking-head video and only need to re-sync its lips to new audio rather than animate a still photo — use a lip-sync (video-to-video) model - You want to animate a scene or object from a text prompt with no driving audio — use an image-to-video or text-to-video model - You need a generic image-to-video clip with no speech and no audio track to drive the motion — use a standard image-to-video model
## Tips - Use a clear, front-facing photo with the full face visible and unobstructed for the most accurate sync - Audio length is capped by resolution: keep audio under 30s at 1080p, under 60s at 720p - Use `prompt` to guide gestures, energy, and camera feel (e.g. "calm presenter, slight head nods"); leave it empty to let the audio drive everything - Set `mask_url` to a mask image when the photo contains more than one person — only the person inside the white region of the mask will be animated to speak - `turbo_mode` trades a little quality for faster generation at no extra cost
## Limitations - Built for human subjects driven by an audio track; non-human subjects or audio with no clear speech/vocal signal give weaker results - Very long clips must be split to stay within the per-resolution audio-duration limits
To run via the ModelRunner JavaScript client: ```js import { modelrunner } from "@modelrunner/client";
const result = await modelrunner.subscribe("bytedance/omnihuman/v1.5", { input: { image_url: "https://media.modelrunner.ai/ho4HXHjCrHjv7MZs-omnihuman_v15_input_image.png", audio_url: "https://media.modelrunner.ai/v293WP0BkvLcoXC3MJLud.mp3", prompt: "natural presenter delivering the line, subtle head movement", resolution: "1080p", }, }); ```